|
| 1 | +{ |
| 2 | + "cells": [ |
| 3 | + { |
| 4 | + "cell_type": "raw", |
| 5 | + "id": "49a58314", |
| 6 | + "metadata": {}, |
| 7 | + "source": [ |
| 8 | + "---\n", |
| 9 | + "title: \"A guide to Generative AI for the working scientist\"\n", |
| 10 | + "date: 2025-10-29\n", |
| 11 | + "author:\n", |
| 12 | + " - name: Charles F. Vardeman II\n", |
| 13 | + " id: cfv\n", |
| 14 | + " orcid: 0000-0002-1825-0097\n", |
| 15 | + " email: cvardema@nd.edu\n", |
| 16 | + " affiliation:\n", |
| 17 | + " - name: Center for Research Computing, University of Notre Dame\n", |
| 18 | + " city: Notre Dame\n", |
| 19 | + " state: IN\n", |
| 20 | + " url: https://crc.nd.edu\n", |
| 21 | + " - name: CI-Compass\n", |
| 22 | + " url: https://ci-compass.org\n", |
| 23 | + "keywords:\n", |
| 24 | + " - Generative AI in Science\n", |
| 25 | + " - Science Agents\n", |
| 26 | + "license: \"CC BY\"\n", |
| 27 | + "citation:\n", |
| 28 | + " type: document\n", |
| 29 | + " container-title: Zenodo\n", |
| 30 | + " doi: 10.5281/zenodo.10815117\n", |
| 31 | + "links:\n", |
| 32 | + " - text: \"Video Presentation\"\n", |
| 33 | + " url: \"https://www.youtube.com/@cicompass\"\n", |
| 34 | + " - text: \"GitHub Repository\"\n", |
| 35 | + " url: \"https://github.com/ci-compass/AI-working-scientist/\"\n", |
| 36 | + "funding: \"This project is supported by the U.S. National Science Foundation Office of Advanced Cyberinfrastructure in the Directorate for Computer Information Science under Grant #2127548\"\n", |
| 37 | + "format:\n", |
| 38 | + " html:\n", |
| 39 | + " toc: true\n", |
| 40 | + " code-fold: true\n", |
| 41 | + "---" |
| 42 | + ] |
| 43 | + }, |
| 44 | + { |
| 45 | + "cell_type": "markdown", |
| 46 | + "id": "49926eb8", |
| 47 | + "metadata": {}, |
| 48 | + "source": [ |
| 49 | + "## GitHub CI-compass Organization\n", |
| 50 | + "- [GitHub Link: https://github.com/ci-compass/AI-working-scientist/tree/main](https://github.com/ci-compass/AI-working-scientist/tree/main)" |
| 51 | + ] |
| 52 | + }, |
| 53 | + { |
| 54 | + "cell_type": "markdown", |
| 55 | + "id": "984505e3", |
| 56 | + "metadata": {}, |
| 57 | + "source": [ |
| 58 | + "# A guide to Generative AI for the Working Scientist\n", |
| 59 | + "\n", |
| 60 | + "> This video is meant to be a rough guide to some of the concepts and to help understand generative AI and preparation for the NSF CyberInfrastructure Center of Excellence [CI-Compass](https://ci-compass.org/) [Virtual Workshop - AI Meets CI: Intelligent Infrastructure for Major & Midscale Facilities](https://ci-compass.org/news-and-events/events/virtual-workshop-ai-meets-ci-intelligent-infrastructure-for-major-and-midscale-facilities/). The purpose is to start from the beginning and try to de-mystify **chatbot** based Generative AI.\n", |
| 61 | + "\n", |
| 62 | + "\n", |
| 63 | + "\n", |
| 64 | + "## Chat based generative AI\n", |
| 65 | + "\n", |
| 66 | + "### Chat interface\n", |
| 67 | + "- [OpenAI ChatGPT](https://chatgpt.com/)\n", |
| 68 | + "- [Anthropic Claude](https://claude.ai/new)\n", |
| 69 | + "- [Google Gemini](https://gemini.google.com/)\n", |
| 70 | + "\n", |
| 71 | + "### Terminal Based Coding Agents\n", |
| 72 | + "- [Anthropic Claude Code Cli](https://www.claude.com/product/claude-code)\n", |
| 73 | + "- [OpenAI Codex Cli](https://github.com/openai/codex)\n", |
| 74 | + "- [Google Gemini Cli](https://geminicli.com/)\n", |
| 75 | + "- [Microsoft Visual Studio Code](https://code.visualstudio.com/)\n", |
| 76 | + "\n", |
| 77 | + "### Notebook Based AI\n", |
| 78 | + "- [AnswerAI SolveIT](https://solve.it.com)\n", |
| 79 | + "- [Google Collab](https://developers.googleblog.com/en/data-science-agent-in-colab-with-gemini/)" |
| 80 | + ] |
| 81 | + }, |
| 82 | + { |
| 83 | + "cell_type": "markdown", |
| 84 | + "id": "b03f9ec9", |
| 85 | + "metadata": {}, |
| 86 | + "source": [ |
| 87 | + "## \"Context Window -- Trained Model\"\n", |
| 88 | + "Think of an LLM as a kind of supercharged text predictor: you give it a sequence of tokens (words or subwords) and it predicts the next token, then the next, etc. What we call the context window is simply how many tokens the model can look back at when making each prediction.\n", |
| 89 | + "\n", |
| 90 | + "- If a model has a context window of, say, 4,096 tokens, then when it’s about to predict token N, it only “knows” about tokens N-4,095 through N-1 (plus whatever internal state) — it cannot directly “see” tokens older than that.\n", |
| 91 | + "\n", |
| 92 | + "- Everything the model uses to ground its prediction must be inside that window — the user prompt, the system instructions, examples, retrieved documents, conversation history, etc." |
| 93 | + ] |
| 94 | + }, |
| 95 | + { |
| 96 | + "cell_type": "markdown", |
| 97 | + "id": "be634c62", |
| 98 | + "metadata": {}, |
| 99 | + "source": [ |
| 100 | + "### Why does the Context Window Matter?\n", |
| 101 | + "1. **Scope of what the model knows in this invocation -- Stateless Model**\n", |
| 102 | + "> Because the model cannot remember everything ever said, only what fits into its window — if you want it to reference a piece of text, you must include it (or a compressed version of it) in the window.\n", |
| 103 | + "\n", |
| 104 | + "2. **Management of context = performance trade-offs**\n", |
| 105 | + "> The more tokens you feed (longer history, more retrieved docs, more examples), the richer the information the model has — but you are limited by the window size. If you exceed it, older tokens get truncated (lost). If you fill it with irrelevant stuff, you can confuse the model (context noise) rather than help it. Karpathy calls this “the delicate art and science of filling the context window with just the right information for the next step.”\n", |
| 106 | + "\n", |
| 107 | + "3. **Analogy: human coworker with short-term memory**\n", |
| 108 | + "> Karpathy uses an analogy: the LLM is like a coworker who has anterograde amnesia — they forget everything beyond a short timeframe. So if you want them to reference something older, you must remind them (i.e., re-include it in the window)." |
| 109 | + ] |
| 110 | + }, |
| 111 | + { |
| 112 | + "cell_type": "markdown", |
| 113 | + "id": "3b7756de", |
| 114 | + "metadata": {}, |
| 115 | + "source": [ |
| 116 | + "## \"Prompt Engineering\" vs \"Context Engineering\"\n", |
| 117 | + "\n", |
| 118 | + "> \"Context refers to the set of tokens included when sampling from a large-language model (LLM). The engineering problem at hand is optimizing the utility of those tokens against the inherent constraints of LLMs in order to consistently achieve a desired outcome. Effectively wrangling LLMs often requires thinking in context — in other words: considering the holistic state available to the LLM at any given time and what potential behaviors that state might yield.\"\n", |
| 119 | + "\n", |
| 120 | + "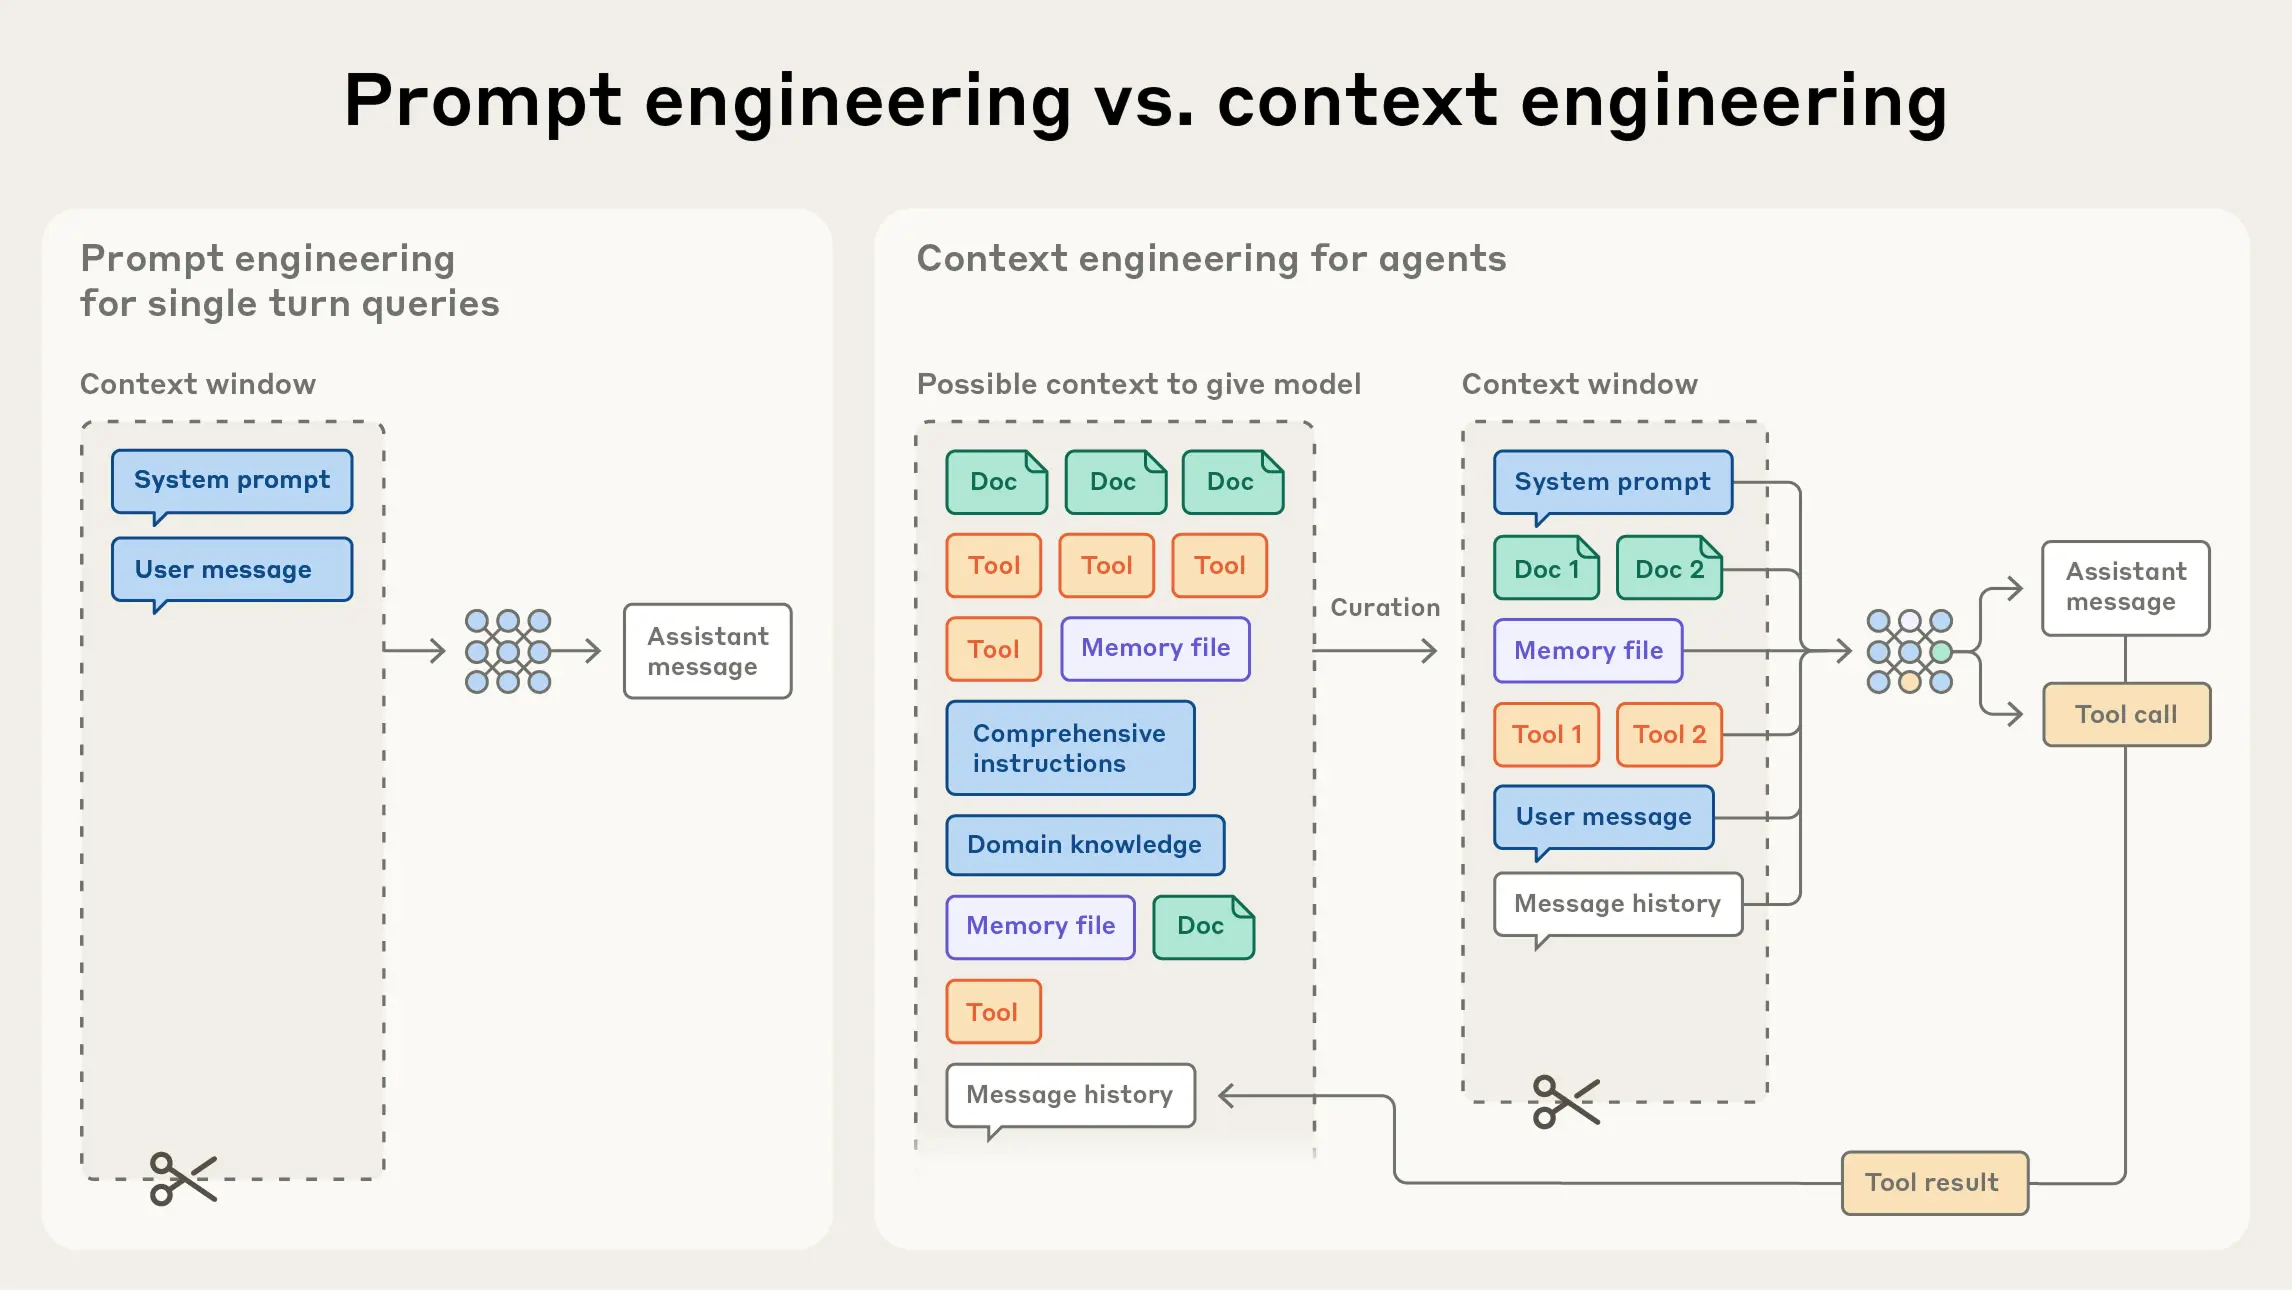\n", |
| 121 | + "---\n", |
| 122 | + "- [Anthropic Engineering, \"Effective context engineering for AI agents\", Sep 29, 2025, https://www.anthropic.com/engineering/effective-context-engineering-for-ai-agents](https://www.anthropic.com/engineering/effective-context-engineering-for-ai-agents)" |
| 123 | + ] |
| 124 | + }, |
| 125 | + { |
| 126 | + "cell_type": "markdown", |
| 127 | + "id": "eb98a0c2", |
| 128 | + "metadata": {}, |
| 129 | + "source": [ |
| 130 | + "### Multimodal Context Window\n", |
| 131 | + ">Now imagine we extend that idea: Instead of feeding the model just text tokens, we also feed in image tokens, audio tokens, video frame tokens, sensor tokens, etc. \n", |
| 132 | + "\n", |
| 133 | + "**Each modality has its own tokenizer:**\n", |
| 134 | + "\n", |
| 135 | + "- Text → word/subword tokens\n", |
| 136 | + "\n", |
| 137 | + "- Images → small patch tokens (like 16×16 pixels each)\n", |
| 138 | + "\n", |
| 139 | + "- Audio → waveform chunks or spectrogram tokens\n", |
| 140 | + "\n", |
| 141 | + "All of those get projected into the same vector space and concatenated into one long sequence.\n", |
| 142 | + "That sequence is the multimodal context window." |
| 143 | + ] |
| 144 | + }, |
| 145 | + { |
| 146 | + "cell_type": "code", |
| 147 | + "execution_count": null, |
| 148 | + "id": "5670dfc0", |
| 149 | + "metadata": { |
| 150 | + "time_run": "5:42:30p" |
| 151 | + }, |
| 152 | + "outputs": [], |
| 153 | + "source": [ |
| 154 | + "from dialoghelper import *\n", |
| 155 | + "fc_tool_info()" |
| 156 | + ] |
| 157 | + }, |
| 158 | + { |
| 159 | + "cell_type": "code", |
| 160 | + "execution_count": null, |
| 161 | + "id": "88ee920c", |
| 162 | + "metadata": {}, |
| 163 | + "outputs": [], |
| 164 | + "source": [ |
| 165 | + "from fastcore.tools import *" |
| 166 | + ] |
| 167 | + }, |
| 168 | + { |
| 169 | + "cell_type": "markdown", |
| 170 | + "id": "4b328965", |
| 171 | + "metadata": { |
| 172 | + "hide_input": true |
| 173 | + }, |
| 174 | + "source": [ |
| 175 | + "Tools available from `fastcore.tools`:\n", |
| 176 | + "\n", |
| 177 | + "- &`rg`: Run the `rg` command with the args in `argstr` (no need to backslash escape)\n", |
| 178 | + "- &`sed`: Run the `sed` command with the args in `argstr` (e.g for reading a section of a file)\n", |
| 179 | + "- &`view`: View directory or file contents with optional line range and numbers\n", |
| 180 | + "- &`create`: Creates a new file with the given content at the specified path\n", |
| 181 | + "- &`insert`: Insert new_str at specified line number\n", |
| 182 | + "- &`str_replace`: Replace first occurrence of old_str with new_str in file\n", |
| 183 | + "- &`strs_replace`: Replace for each str pair in old_strs,new_strs\n", |
| 184 | + "- &`replace_lines`: Replace lines in file using start and end line-numbers" |
| 185 | + ] |
| 186 | + }, |
| 187 | + { |
| 188 | + "cell_type": "code", |
| 189 | + "execution_count": null, |
| 190 | + "id": "03bd1f3e", |
| 191 | + "metadata": { |
| 192 | + "time_run": "5:42:30p" |
| 193 | + }, |
| 194 | + "outputs": [], |
| 195 | + "source": [ |
| 196 | + "from fastcore.tools import *" |
| 197 | + ] |
| 198 | + }, |
| 199 | + { |
| 200 | + "cell_type": "markdown", |
| 201 | + "id": "38dfc81e", |
| 202 | + "metadata": { |
| 203 | + "hide_input": true |
| 204 | + }, |
| 205 | + "source": [ |
| 206 | + "Tools available from `fastcore.tools`:\n", |
| 207 | + "\n", |
| 208 | + "- &`rg`: Run the `rg` command with the args in `argstr` (no need to backslash escape)\n", |
| 209 | + "- &`sed`: Run the `sed` command with the args in `argstr` (e.g for reading a section of a file)\n", |
| 210 | + "- &`view`: View directory or file contents with optional line range and numbers\n", |
| 211 | + "- &`create`: Creates a new file with the given content at the specified path\n", |
| 212 | + "- &`insert`: Insert new_str at specified line number\n", |
| 213 | + "- &`str_replace`: Replace first occurrence of old_str with new_str in file\n", |
| 214 | + "- &`strs_replace`: Replace for each str pair in old_strs,new_strs\n", |
| 215 | + "- &`replace_lines`: Replace lines in file using start and end line-numbers" |
| 216 | + ] |
| 217 | + }, |
| 218 | + { |
| 219 | + "cell_type": "code", |
| 220 | + "execution_count": null, |
| 221 | + "id": "5ec67704", |
| 222 | + "metadata": { |
| 223 | + "time_run": "5:42:30p" |
| 224 | + }, |
| 225 | + "outputs": [], |
| 226 | + "source": [ |
| 227 | + "tool_info()" |
| 228 | + ] |
| 229 | + }, |
| 230 | + { |
| 231 | + "cell_type": "markdown", |
| 232 | + "id": "19f2dd6f", |
| 233 | + "metadata": { |
| 234 | + "hide_input": true |
| 235 | + }, |
| 236 | + "source": [ |
| 237 | + "Tools available from `dialoghelper`:\n", |
| 238 | + "\n", |
| 239 | + "- &`curr_dialog`: Get the current dialog info.\n", |
| 240 | + "- &`msg_idx`: Get absolute index of message in dialog.\n", |
| 241 | + "- &`add_html`: Send HTML to the browser to be swapped into the DOM using hx-swap-oob.\n", |
| 242 | + "- &`find_msg_id`: Get the current message id.\n", |
| 243 | + "- &`find_msgs`: Find messages in current specific dialog that contain the given information.\n", |
| 244 | + " - (solveit can often get this id directly from its context, and will not need to use this if the required information is already available to it.)\n", |
| 245 | + "- &`read_msg`: Get the message indexed in the current dialog.\n", |
| 246 | + " - To get the exact message use `n=0` and `relative=True` together with `msgid`.\n", |
| 247 | + " - To get a relative message use `n` (relative position index).\n", |
| 248 | + " - To get the nth message use `n` with `relative=False`, e.g `n=0` first message, `n=-1` last message.\n", |
| 249 | + "- &`del_msg`: Delete a message from the dialog.\n", |
| 250 | + "- &`add_msg`: Add/update a message to the queue to show after code execution completes.\n", |
| 251 | + "- &`update_msg`: Update an existing message.\n", |
| 252 | + "- &`url2note`: Read URL as markdown, and add a note below current message with the result\n", |
| 253 | + "- &`msg_insert_line`: Insert text at a specific location in a message.\n", |
| 254 | + "- &`msg_str_replace`: Find and replace text in a message.\n", |
| 255 | + "- &`msg_strs_replace`: Find and replace multiple strings in a message.\n", |
| 256 | + "- &`msg_replace_lines`: Replace a range of lines in a message with new content.\n", |
| 257 | + " - Always first use `read_msg( msgid=msgid, n=0, relative=True, nums=True)` to view the content with line numbers." |
| 258 | + ] |
| 259 | + }, |
| 260 | + { |
| 261 | + "cell_type": "markdown", |
| 262 | + "id": "f7ff4bef", |
| 263 | + "metadata": {}, |
| 264 | + "source": [ |
| 265 | + "### \"Thinking Models and Chain of Thought\" (Deepseek-R1 from Karpathy Video)\n", |
| 266 | + "\n", |
| 267 | + "\n", |
| 268 | + "- [Language Models Perform Reasoning via Chain of Thought (May 2022)https://research.google/blog/language-models-perform-reasoning-via-chain-of-thought/](https://research.google/blog/language-models-perform-reasoning-via-chain-of-thought/)" |
| 269 | + ] |
| 270 | + }, |
| 271 | + { |
| 272 | + "cell_type": "markdown", |
| 273 | + "id": "f4c7145b", |
| 274 | + "metadata": {}, |
| 275 | + "source": [ |
| 276 | + "## ReACT\n", |
| 277 | + "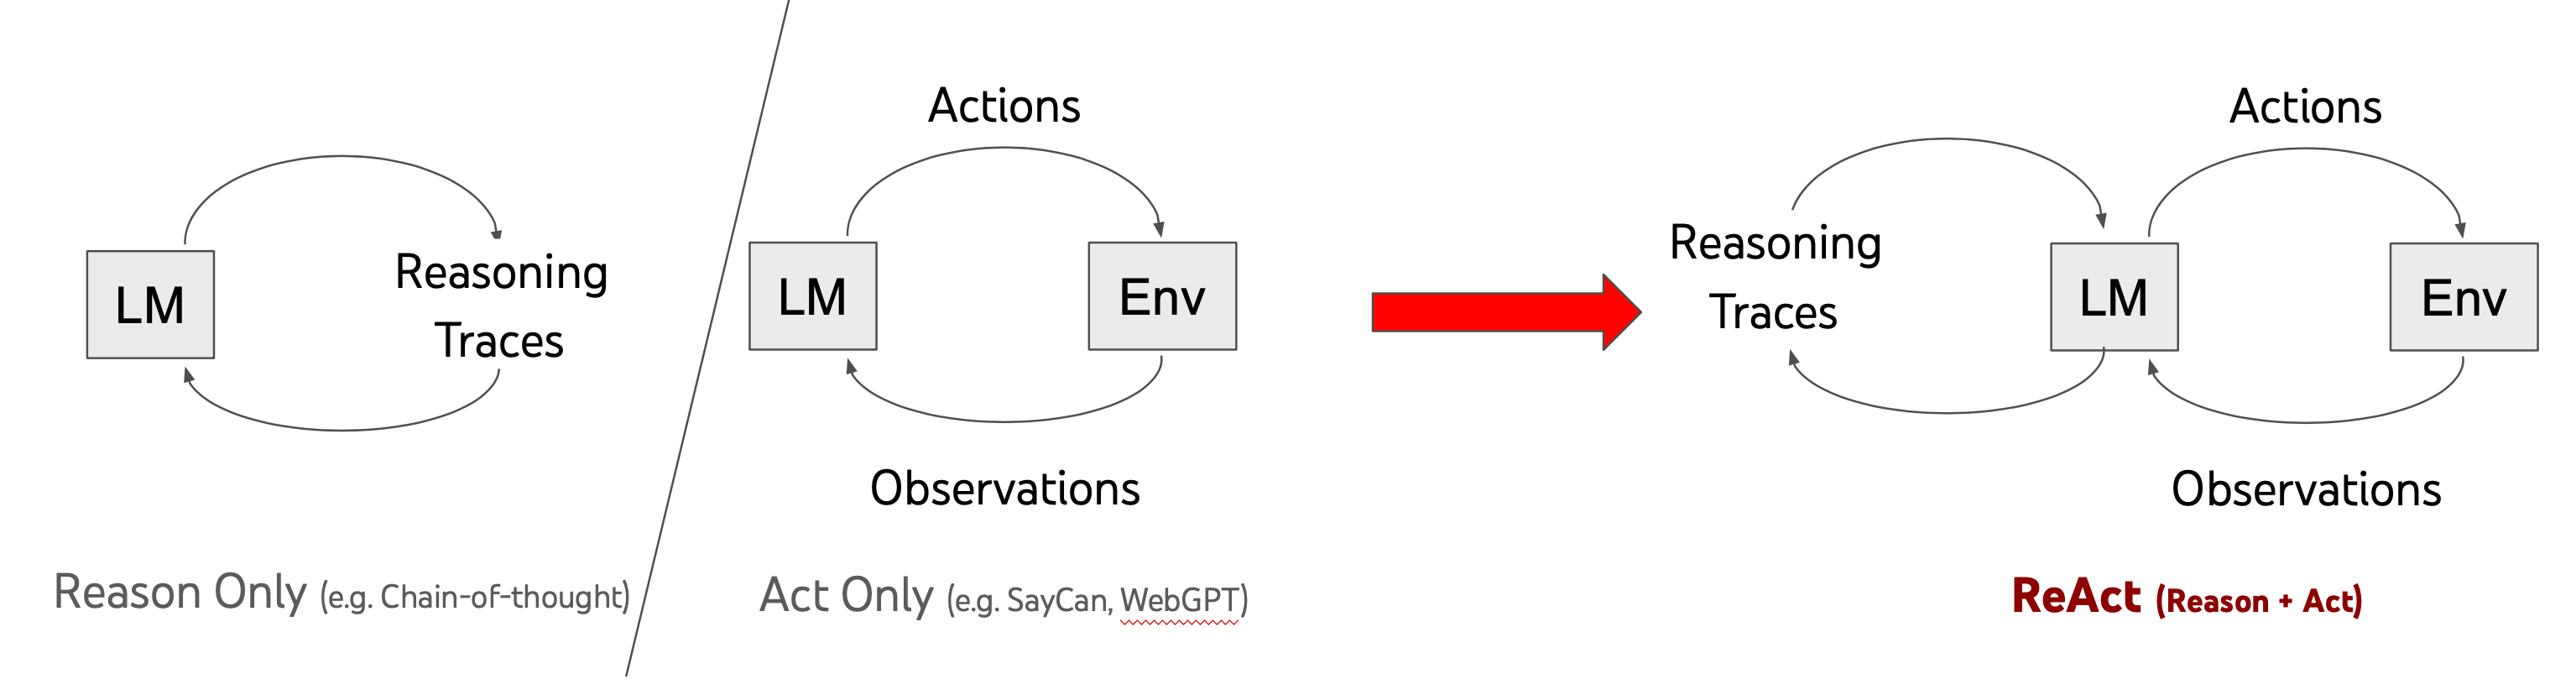\n", |
| 278 | + "\n", |
| 279 | + "- [ReAct: Synergizing Reasoning and Acting in Language Models Blog: https://react-lm.github.io/](https://react-lm.github.io/)\n", |
| 280 | + "- [S. Yao et al., “ReAct: Synergizing reasoning and acting in language models,” Int Conf Learn Represent, vol. abs/2210.03629, Oct. 2022. https://openreview.net/forum?id=WE_vluYUL-X](https://openreview.net/forum?id=WE_vluYUL-X)" |
| 281 | + ] |
| 282 | + } |
| 283 | + ], |
| 284 | + "metadata": { |
| 285 | + "solveit_dialog_mode": "learning", |
| 286 | + "solveit_ver": 2 |
| 287 | + }, |
| 288 | + "nbformat": 4, |
| 289 | + "nbformat_minor": 5 |
| 290 | +} |

0 commit comments