I'm an MSc researcher in Computer Engineering (AI) at the University of Genoa,
working as a Research Assistant at CNR within the EU Horizon Europe project REXASI-PRO.
My thesis investigates the reliability of pretrained neural motion prediction models
for autonomous wheelchair navigation — understanding when and why they fail under varying input conditions.
⭐ TrustRAG — Evidence-Aware Evaluation and Failure Attribution for RAG
Primary research project. Empirical study + reproducible evaluation framework.


RAG evaluations report whether a chunk from the right document was retrieved. That is not the same question as whether the passage supporting the answer reached the generator — and the difference decides which pipeline stage a failure is charged to.
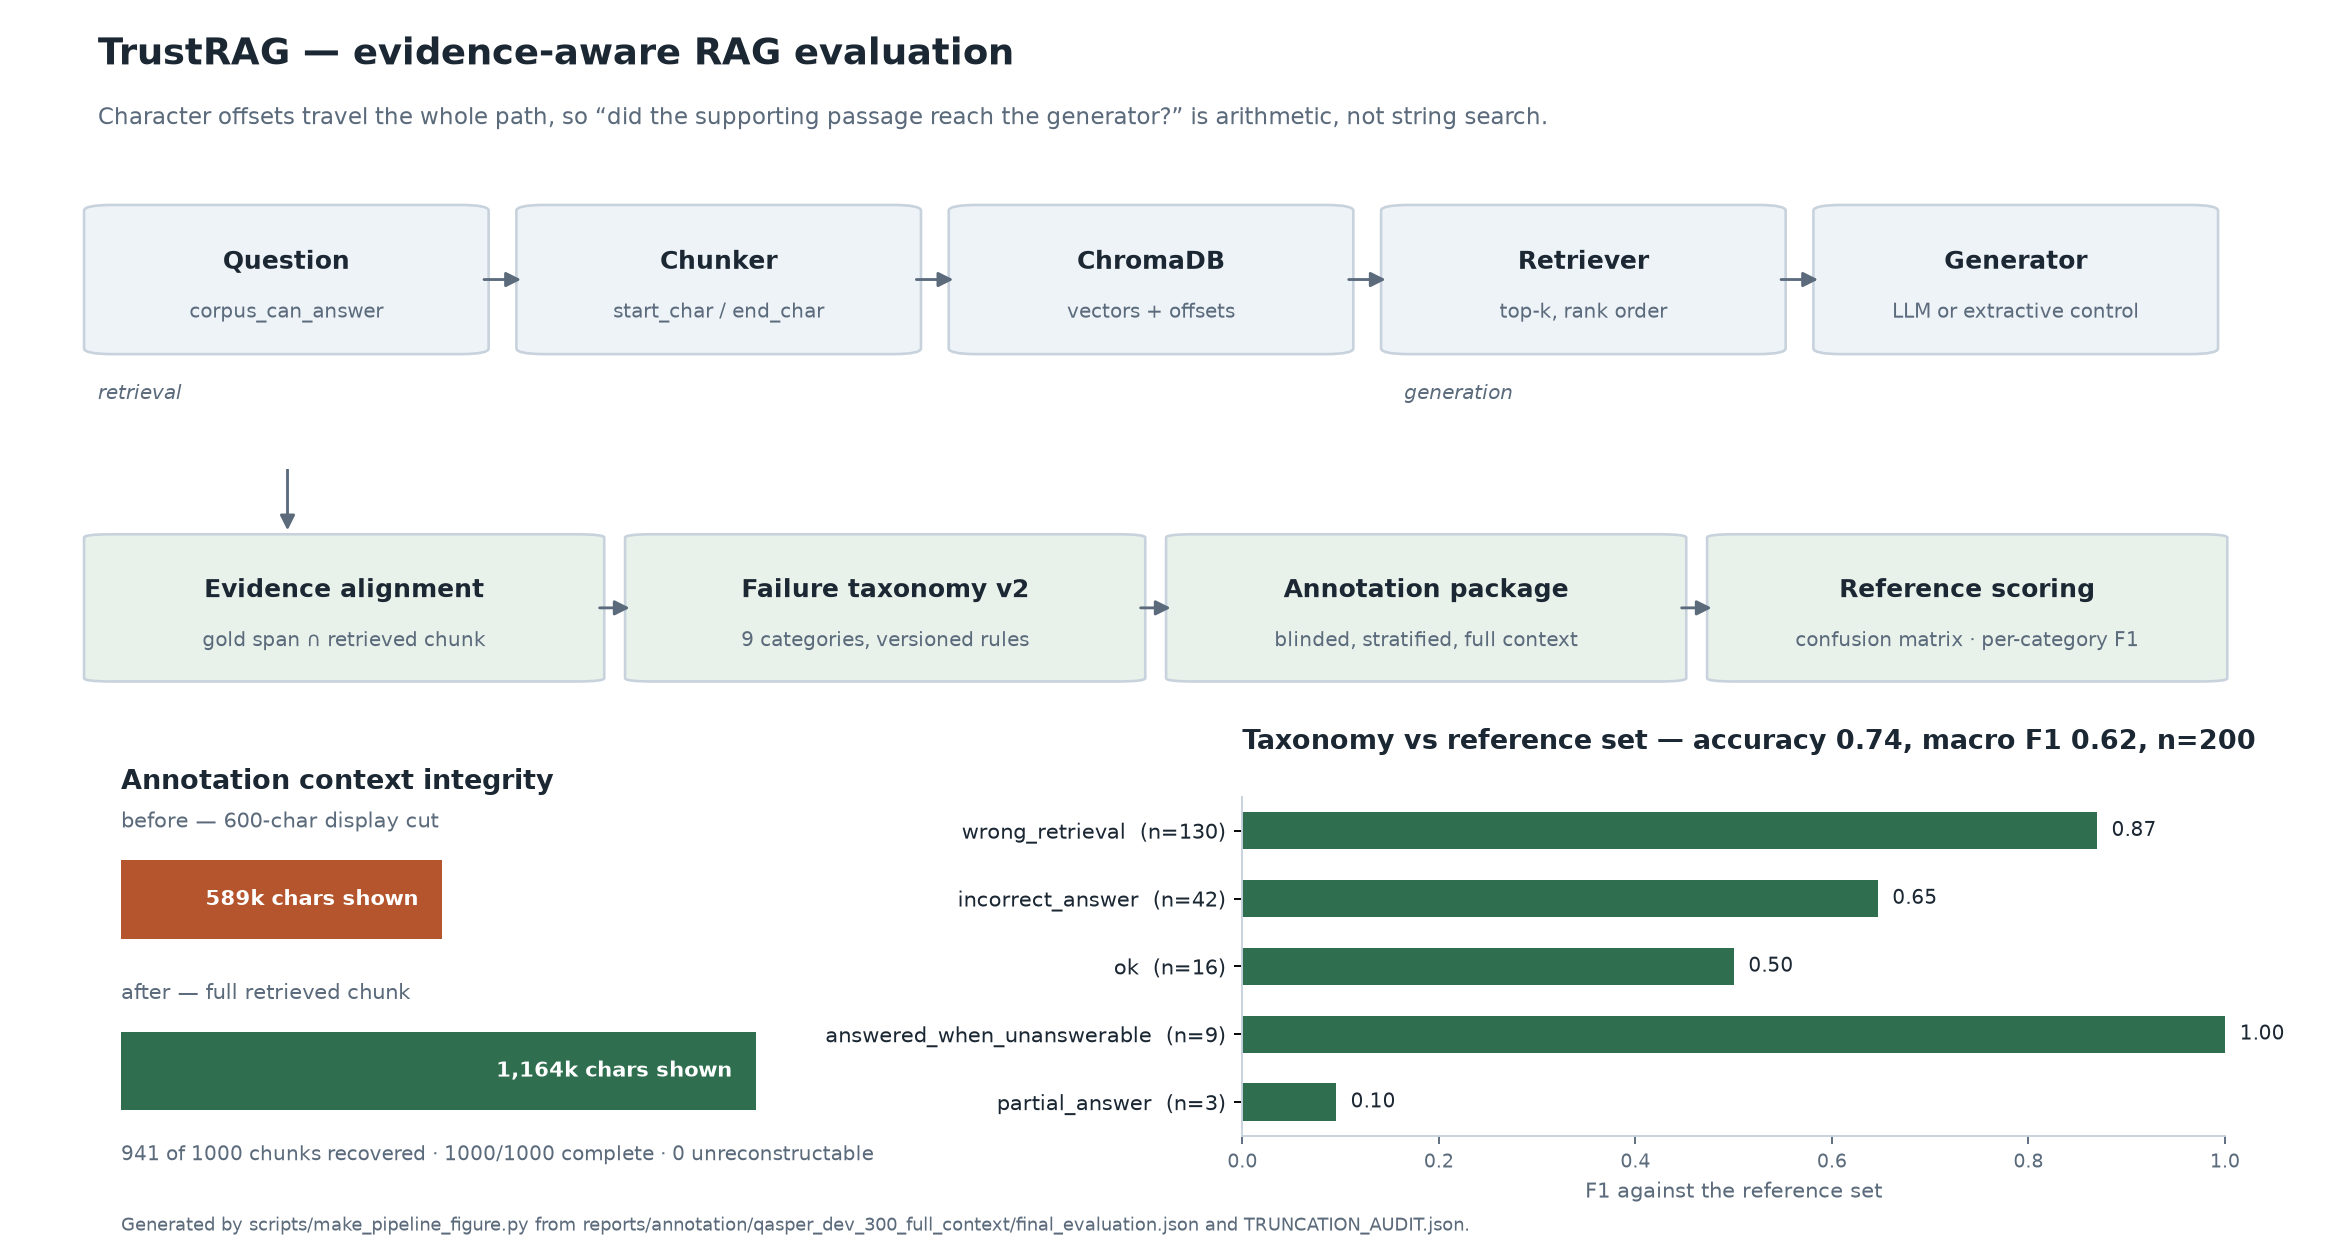
Findings, measured on four public corpora (QASPER, Natural Questions, HotpotQA, 2WikiMultihopQA):
- Attribution flips with the definition of retrieval success. On Natural Questions, the same stored run charges 1 of 300 failures to retrieval at document level and 81 at evidence level.
- Two separable blind spots. A granularity gap on long documents (16.6–26.7 pp, p < 1e-14) and a quantifier gap on multi-hop questions (48.7 pp on HotpotQA, replicated at 64.7 pp on 2WikiMultihopQA), each null where the other dominates — robust across 4 embedders, 5 retrieval depths and 4 chunk sizes.
- Evidence-gated attribution agrees better with an independent human annotation Scored against the same 200 human-annotated units: accuracy 0.805 vs 0.740, Cohen's kappa 0.631 vs 0.573, exact McNemar p = 0.0294 (22 vs 9 discordant). Of the 30 units the document gate misattributes to generation, 22 had no gold evidence retrieved at all.
- A measurement-integrity finding. A 600-character display truncation in the annotation tool hid ~49% of the retrieved evidence (941/1000 chunks) and biased labels toward blaming retrieval. Audited, fixed, and regression-tested; restoring full context moved 13 of 200 labels, all in the predicted direction.
Method: character offsets carried chunker → vector store → retrieval, so evidence coverage is interval arithmetic rather than string matching; a 9-category versioned failure taxonomy with the fired rule recorded per row; blinded stratified annotation packages with an offline annotation tool; Wilson intervals, bootstrap and exact McNemar throughout.
Provenance note: the 200-unit reference annotation was produced by human annotators following the written guidelines, using the full-context blinded annotation interface. The repository reports agreement with this independent human annotation and uses it as the reference set for evaluation
Stack: Python · FastAPI · ChromaDB · sentence-transformers · Docker · GitHub Actions · pytest · Prometheus
📊 Repository · 📄 Research documentation · 🧭 Failure taxonomy · 🔬 Experiments
🔹 Trajectory Failure Analysis — Interpretable Risk Modeling for Motion Prediction
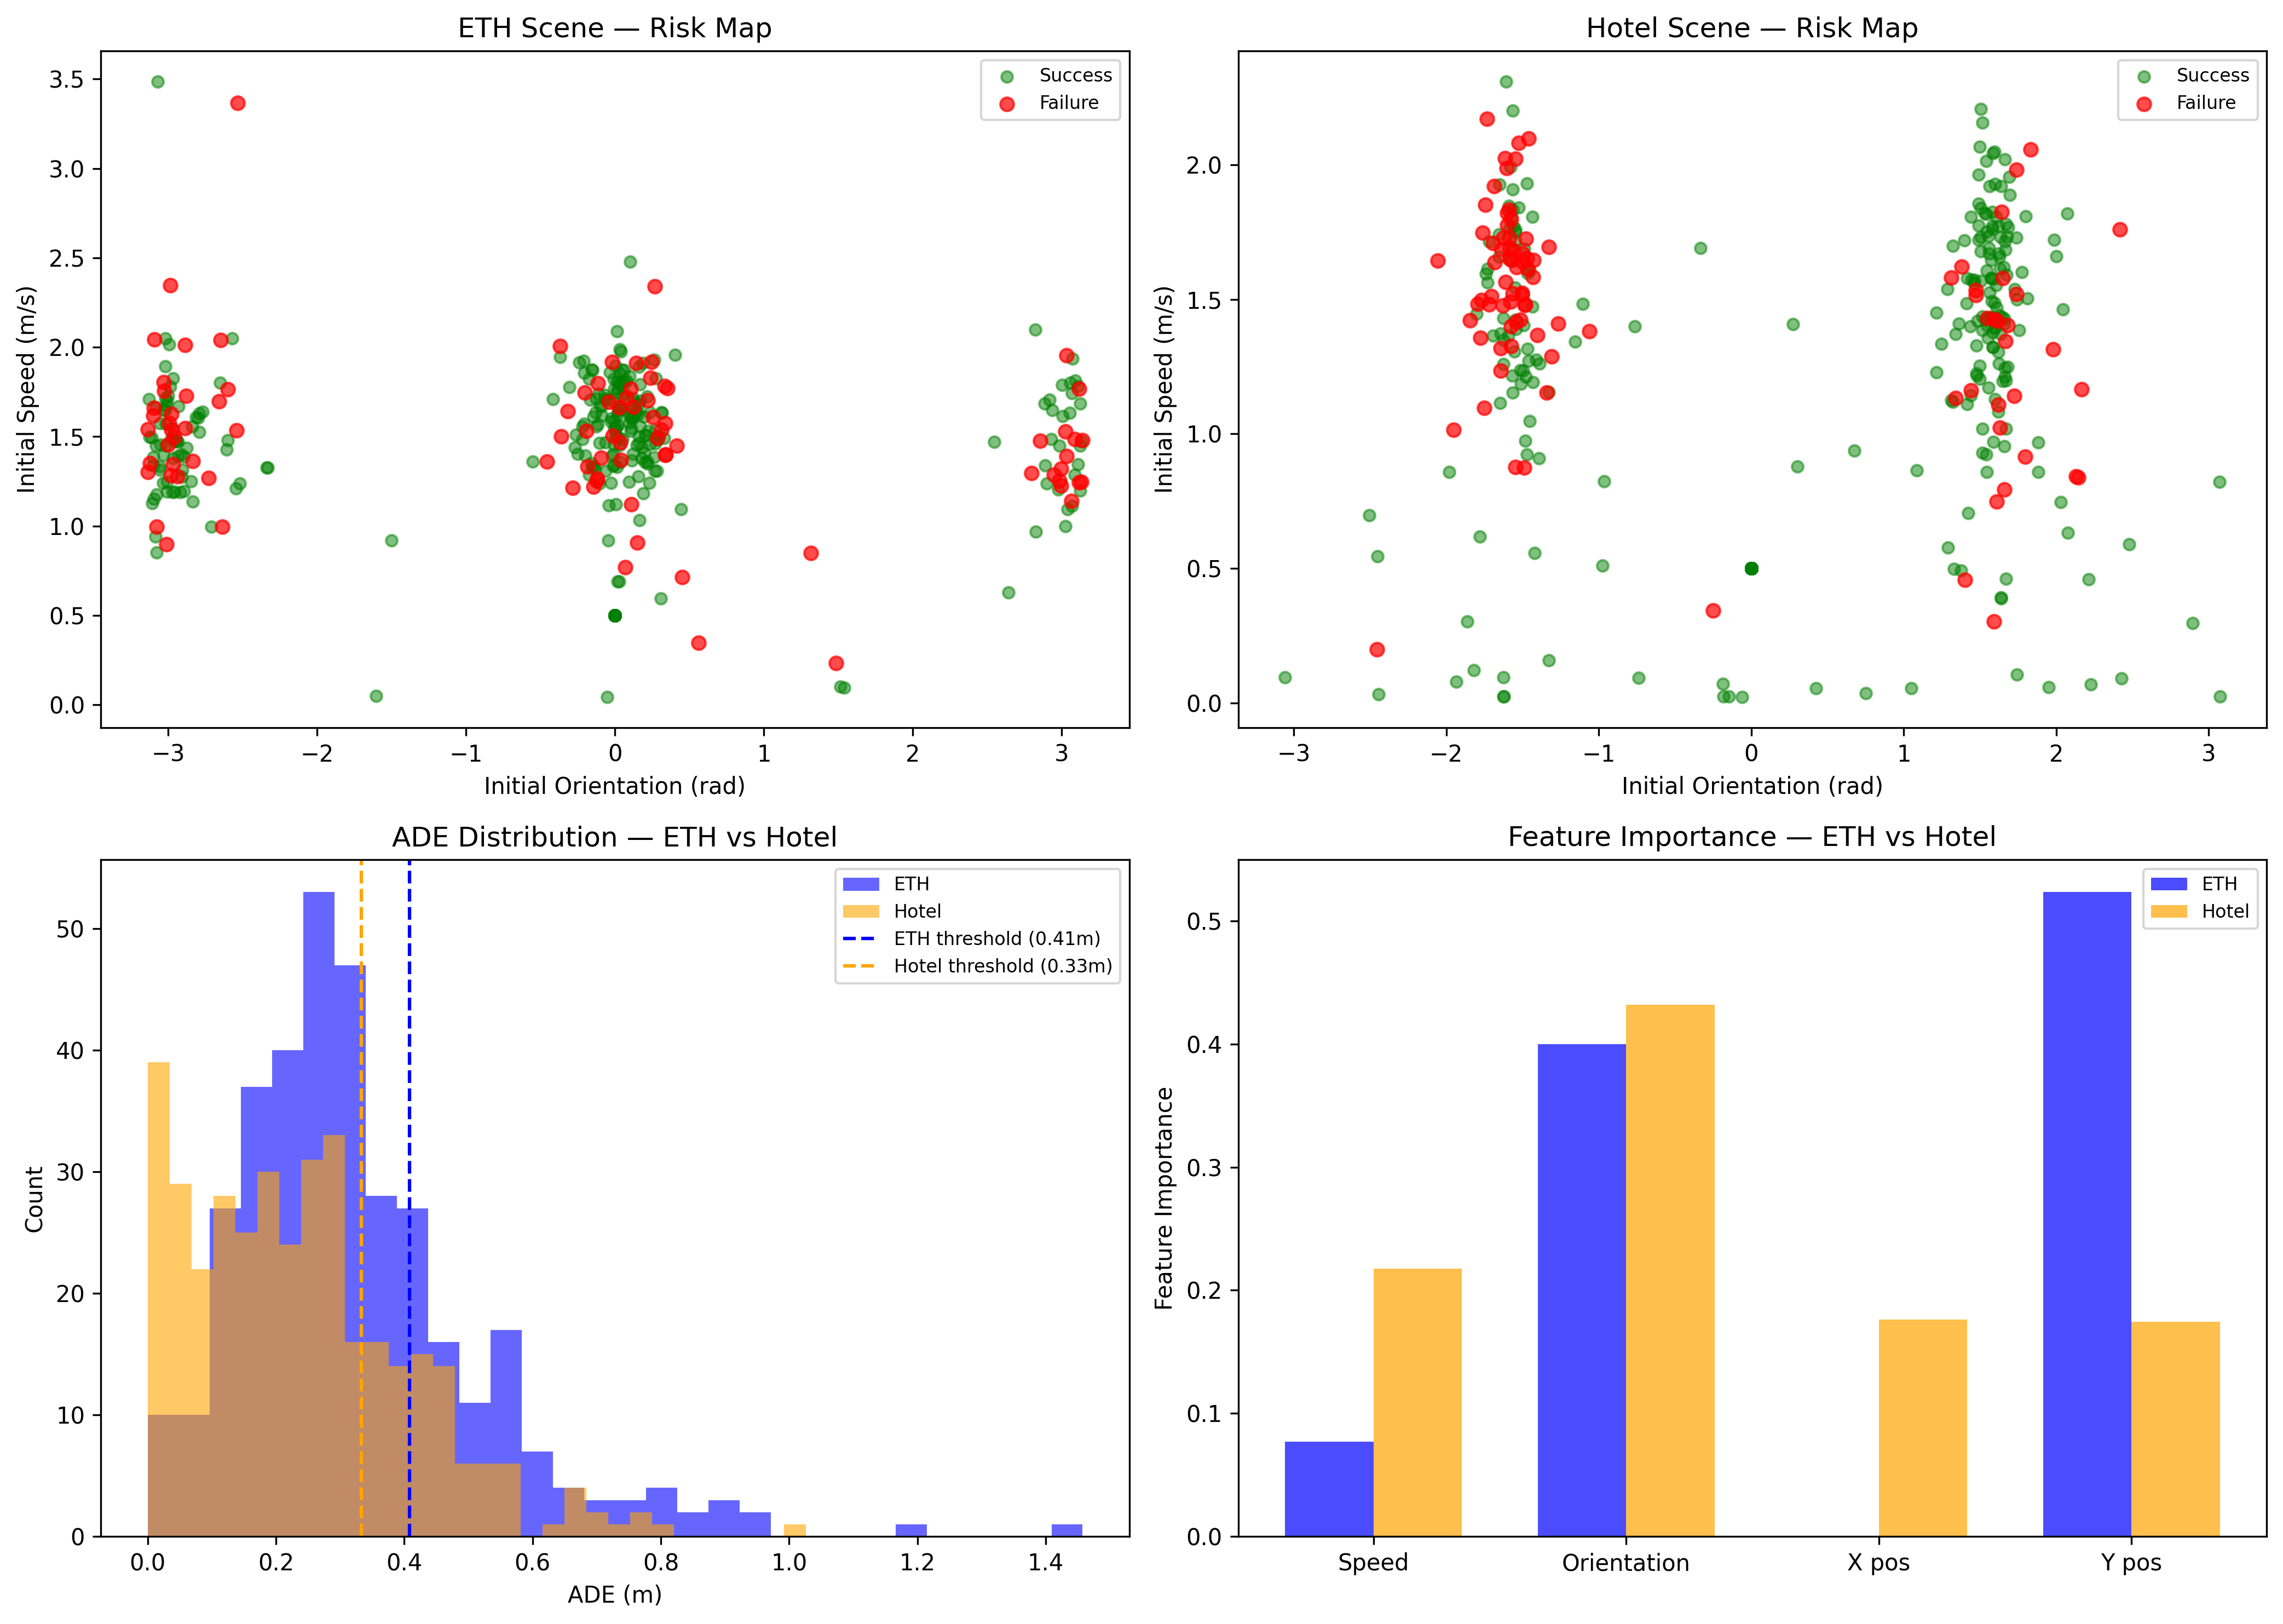
Preprint (PDF available) — ETH Pedestrian Dataset
A model-agnostic framework for analyzing failure modes in trajectory prediction systems, evaluated on real-world pedestrian data.
- Input-space sensitivity analysis (orientation–velocity risk regions)
- Interpretable decision tree models for failure rule extraction
- Cross-scene generalization analysis (ETH vs Hotel)
Key Insight: Initial orientation is a dominant global risk factor, while positional features are scene-dependent — indicating limited transferability of failure rules.
📄 Read Paper
📊 Code & Experiments
MSc Thesis — University of Genoa / CNR / REXASI-PRO
Trajectory-level analysis of pretrained DNN-LNA models for autonomous wheelchair navigation, focusing on reliability, failure analysis, and interpretable evaluation.
- Input-space sensitivity analysis identifying critical failure regions
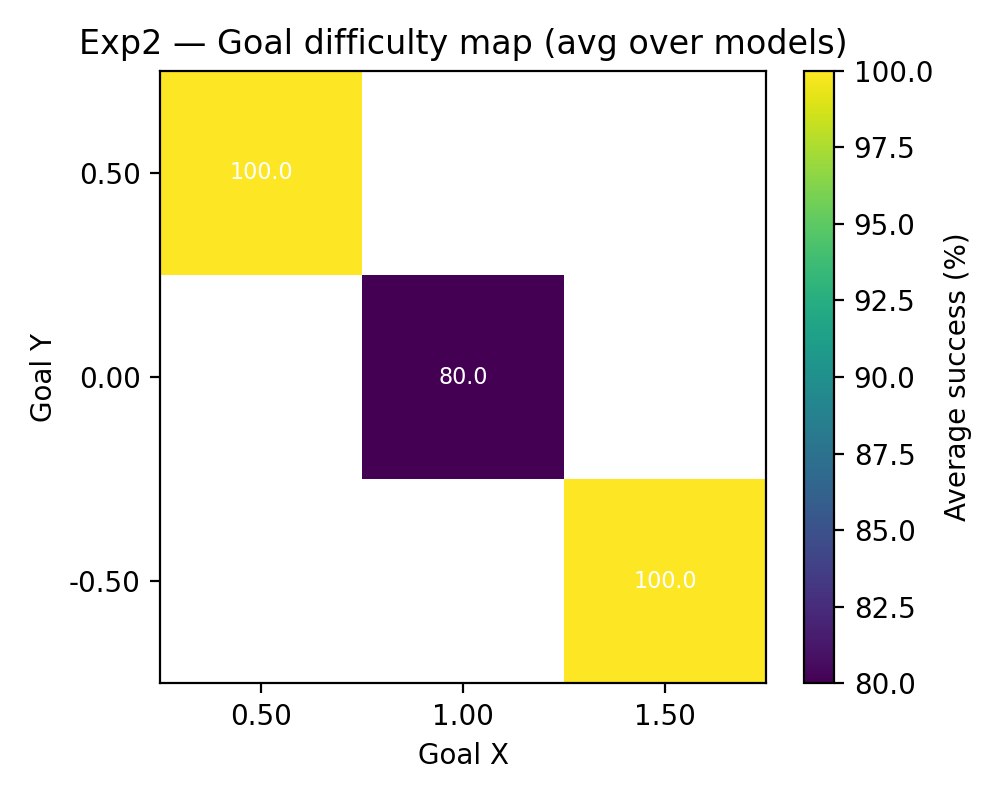
- Goal-based difficulty mapping across the navigation workspace
- Explainable failure modelling using Decision Trees
- Comparative evaluation of 5 DNN-LNA models (25.3%–99.3% success rate)
Demo:

Trajectory Behaviour Analysis Toolkit
Modular Python toolkit for trajectory risk scoring, failure-case analysis, and interpretable ML explanations.
Includes an interactive Streamlit dashboard — try it live!
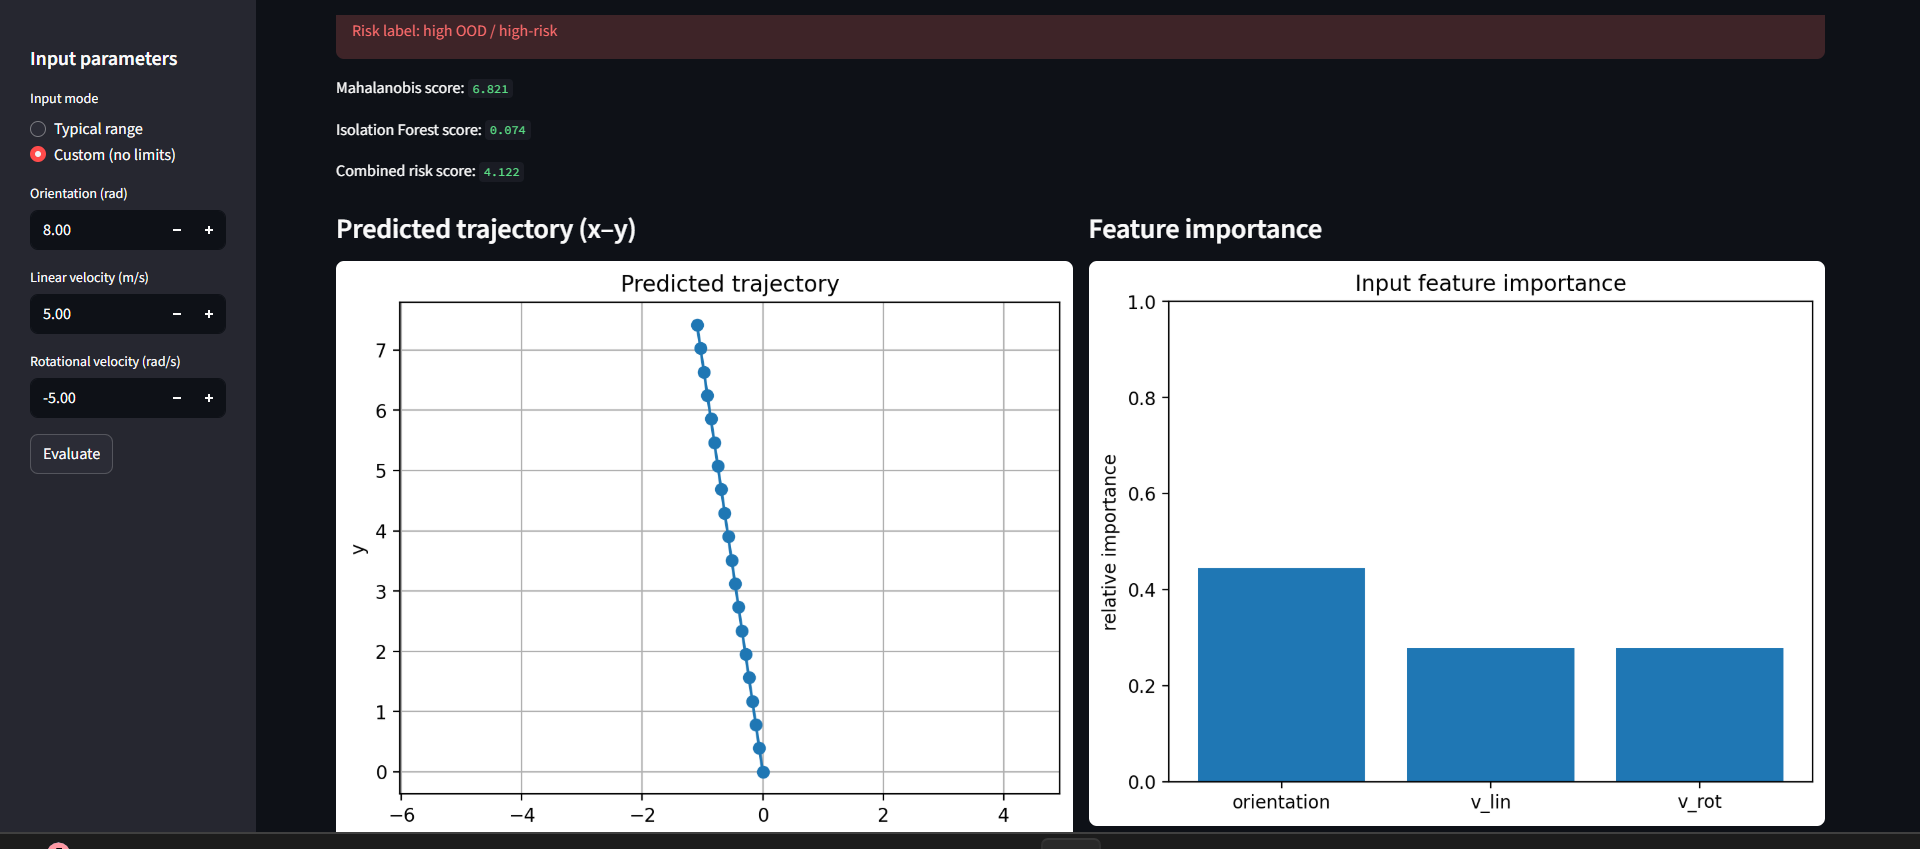
- REST API endpoint for trajectory risk scoring (FastAPI)
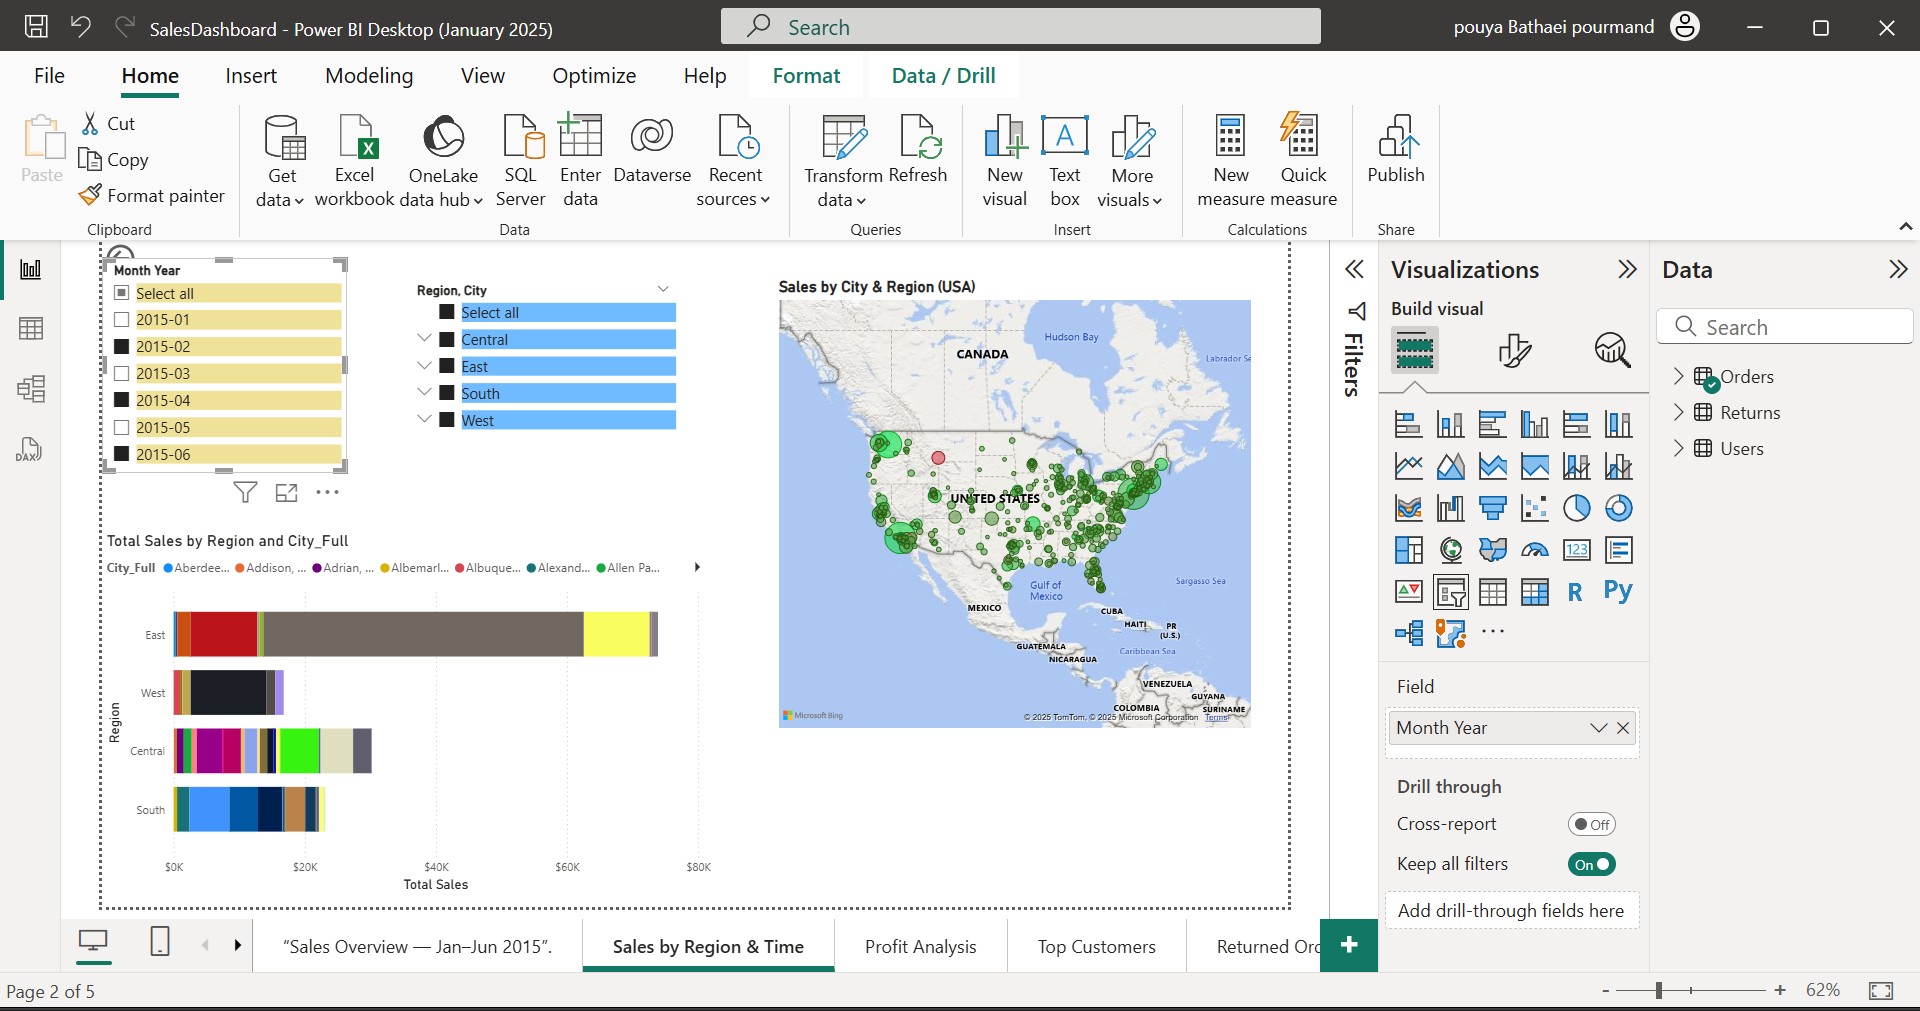
End-to-end BI workflow — Python, SQL, and Power BI dashboard.
AI & ML — Python · PyTorch · scikit-learn · NumPy · pandas
LLM & RAG — OpenAI API · Anthropic API · ChromaDB · sentence-transformers · FastAPI
MLOps — Docker · GitHub Actions CI · pytest · Prometheus · structlog . Git