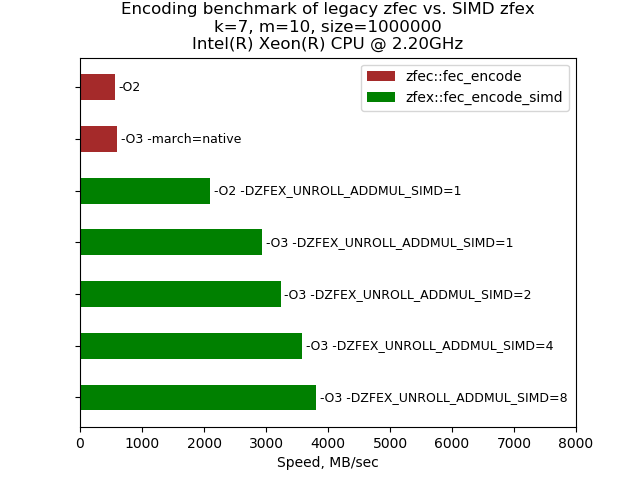
zfex (also on PyPI) is a performance-focused fork of zfec exploiting SIMD for both, Intel and ARM, with impressive results:
Legacy zfec had both results slightly above 50 MB/sec. zfex in all cases ran faster, achieving best performance with -DZFEX_UNROLL_ADDMUL_SIMD=4 unrolling, giving almost 6-fold speed-up.
Having an automatic and seamless way to pick faster versions of the algorithm if the hardware capabilities are available would be really neat.
zfex (also on PyPI) is a performance-focused fork of zfec exploiting SIMD for both, Intel and ARM, with impressive results:
Having an automatic and seamless way to pick faster versions of the algorithm if the hardware capabilities are available would be really neat.